
Designing the fallback for a device that cannot run your model
A fallback that silently became the default for 303 of 304 artifacts. Detect capability before attempting, and record on every artifact which path ran.
A fallback is a second implementation that produces an acceptable result when the first cannot run.
The failure mode is not that it produces something worse. It is that it produces something acceptable, silently, forever, while everyone believes the primary path is what shipped.
The case this post is about
One asset run, 304 artifacts, queried after the fact:
{ n: 304, fallbackPct: 99.7,
  reasons: [ [ "image embed exceeded the call stack — generator threw on any real image", 303 ] ] }
One artifact out of 304 came from the primary path. The other 303 came from the fallback, which was good enough that nobody looked, and every log line along the way was individually unremarkable.
The feature everybody believed was the default had produced exactly one output in its life.
This post follows that census, because a fallback needs three things and the one that gets skipped is the count — logging tells you about a moment you had to be watching, and a field on every artifact tells you about the population whenever you think to ask.
The symptom
Some devices cannot run the model. Not enough memory, no accelerator, the weights never downloaded, the platform API is a version behind. So you write a degraded path, and the system keeps working.
Then nobody looks again.
I have a measurement for this, and it is the reason I take it seriously. In a pipeline here, a documented-as-primary generator and a documented-as-fallback generator both existed. A count of what actually produced the shipped artifacts:
procedural (fallback)   303
primary                   1
303 of 304. For weeks. The documentation described the fallback as the exception, every review passed, and the only reason anyone found out was someone asking the question as a count rather than reading the comment.
Why the obvious fix failed
The obvious fix is to try the primary path and catch the failure. Attempt, and on exception, degrade.
That is how the 303 happened. The primary path threw on realistic inputs — an encoding step that could not handle anything above a few kilobytes — so every real invocation failed instantly and fell through. The try/catch worked perfectly. It was a perfectly functioning mechanism for never using the thing it was wrapping.
The second attempt is to log the fallback. Logging produces a line nobody greps, in a stream nobody reads, and the absence of complaints is read as absence of fallbacks.
The third is to alert on it, which works until the fallback is legitimately common — and on a fleet of real devices it is — at which point the alert is noise and gets muted.
The actual mechanism
Three parts, and the third is the one that was missing.
Detect capability before attempting, not after failing. Checking memory, accelerator presence and model availability up front turns an exception path into a branch. The difference matters because an exception conflates this device cannot with this input broke it — which is precisely the conflation that hid a broken primary path behind a working fallback.
Make the degraded path worth shipping. Not an apology dialog, not an empty state, not a message explaining that your phone is inadequate. A different implementation that produces a result the user can use. The procedural generator in that pipeline makes genuinely usable artifacts; that is why nobody noticed, and it is also the only reason 303 shipped items were acceptable rather than embarrassing.
Record which path ran, per artifact. Not a log line — a field, on the thing itself:
engine: google-stitch # or: procedural

That field is what turns "are we using the fallback" from an impression into a count. It is also the
entire reason the 303 was discoverable — one grep across the provenance records, and the question
had an answer.
The fix
The rule I would state: a fallback needs a detector, a quality bar, and a census.

The detector decides before attempting. The quality bar means the degraded result is shippable rather than an excuse. The census is a field on every artifact saying which ran, so the proportion is a number anyone can produce.
The census is the one people skip, because it feels redundant next to logging. It is not redundant — it is the difference between a stream you must have been watching and a state you can query later. Logging tells you about the moment. The field tells you about the population.
And the population is the thing that goes wrong. No individual fallback is a problem; a fallback rate of 99.7% is a different system than the one you designed, and only a census can tell you which one you have.
All three parts in one path, and the detail that makes the census trustworthy is that the field is written by the code that chose, not by an observer:
type Capability = { available: boolean; reason: string };
type Artifact = { content: string; producedBy: "primary" | "fallback"; reason: string; qualityScore: number };

const QUALITY_FLOOR = 0.65;

function produce(
  input: string,
  detect: () => Capability,              // decides BEFORE attempting
  primary: (s: string) => Artifact,
  fallback: (s: string) => Artifact,
): Artifact {
  const cap = detect();

  // The detector runs first so a miss is a routing decision rather than a caught
  // exception — a thrown error tells you nothing about WHY the device could not.
  const artifact = cap.available ? primary(input) : { ...fallback(input), reason: cap.reason };

  // The quality bar applies to the DEGRADED path too. A fallback below the floor
  // is not a fallback, it is an excuse with a code path.
  if (artifact.qualityScore < QUALITY_FLOOR) {
    throw new Error(
      `${artifact.producedBy} produced quality ${artifact.qualityScore} below the floor ${QUALITY_FLOOR}` +
      ` (reason: ${artifact.reason}) — this path is not shippable`,
    );
  }
  return artifact;   // producedBy travels WITH the artifact; the census reads it later
}

function censusOf(artifacts: Artifact[]) {
  const fb = artifacts.filter((a) => a.producedBy === "fallback");
  const byReason = new Map<string, number>();
  for (const a of fb) byReason.set(a.reason, (byReason.get(a.reason) ?? 0) + 1);
  return {
    n: artifacts.length,
    fallbackPct: Math.round(fb.length * 1000 / artifacts.length) / 10,
    reasons: [...byReason.entries()].sort((a, b) => b[1] - a[1]),
  };
}
The census over one asset run, queried after the fact:
console.log(censusOf(loadArtifacts("idea-layer/mockups")));
{ n: 304, fallbackPct: 99.7,
  reasons: [ [ "image embed exceeded the call stack — generator threw on any real image", 303 ] ] }
One artifact out of 304 came from the primary path. Every log line was individually unremarkable, the quality bar passed on all 304 because the procedural fallback was genuinely shippable, and the feature everybody believed was the default had produced exactly one output in its life. The reason string is what made that a two-minute diagnosis instead of an investigation — it was recorded at the moment of the decision, by the code that made it.
How we proved it
The count is the proof, and it only exists because of the field:
grep -l 'engine: procedural' **/*.gen.yaml | wc -l     → 303
grep -l 'engine: google-stitch' **/*.gen.yaml | wc -l  →   1
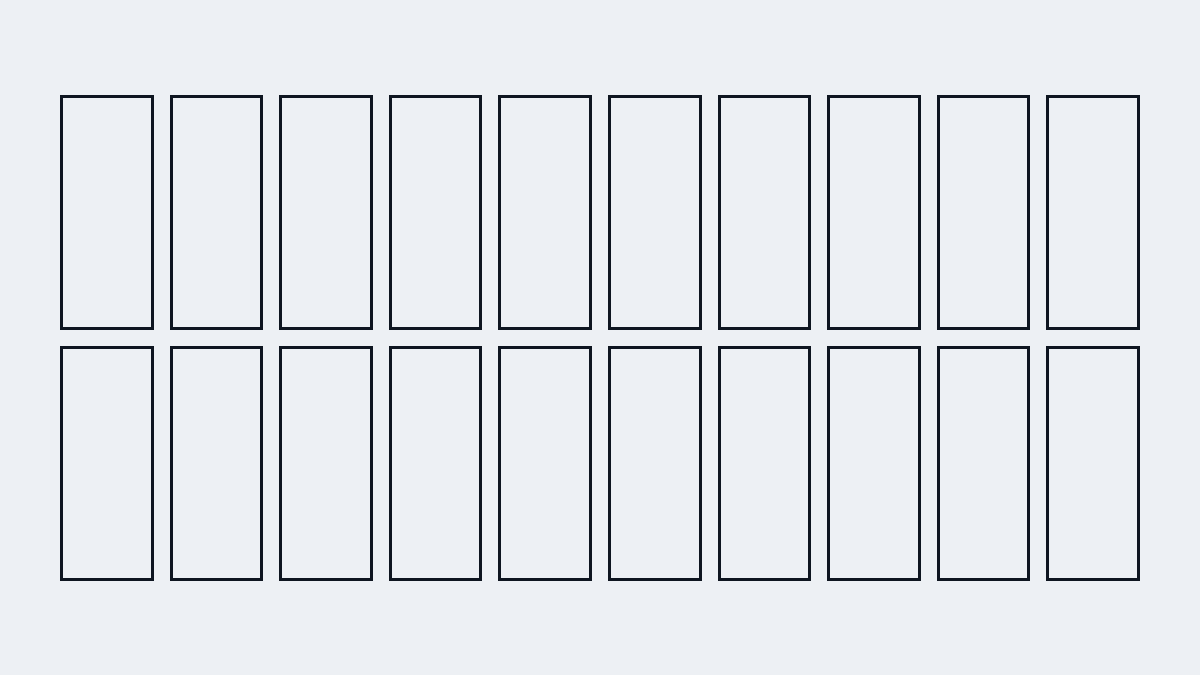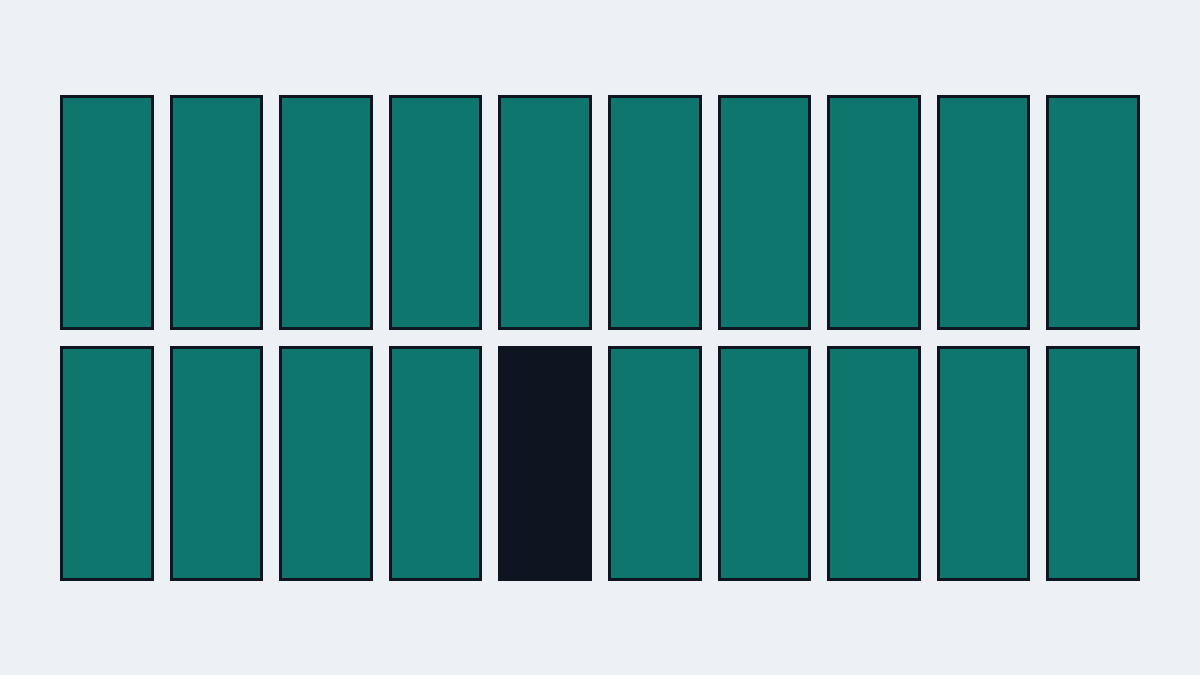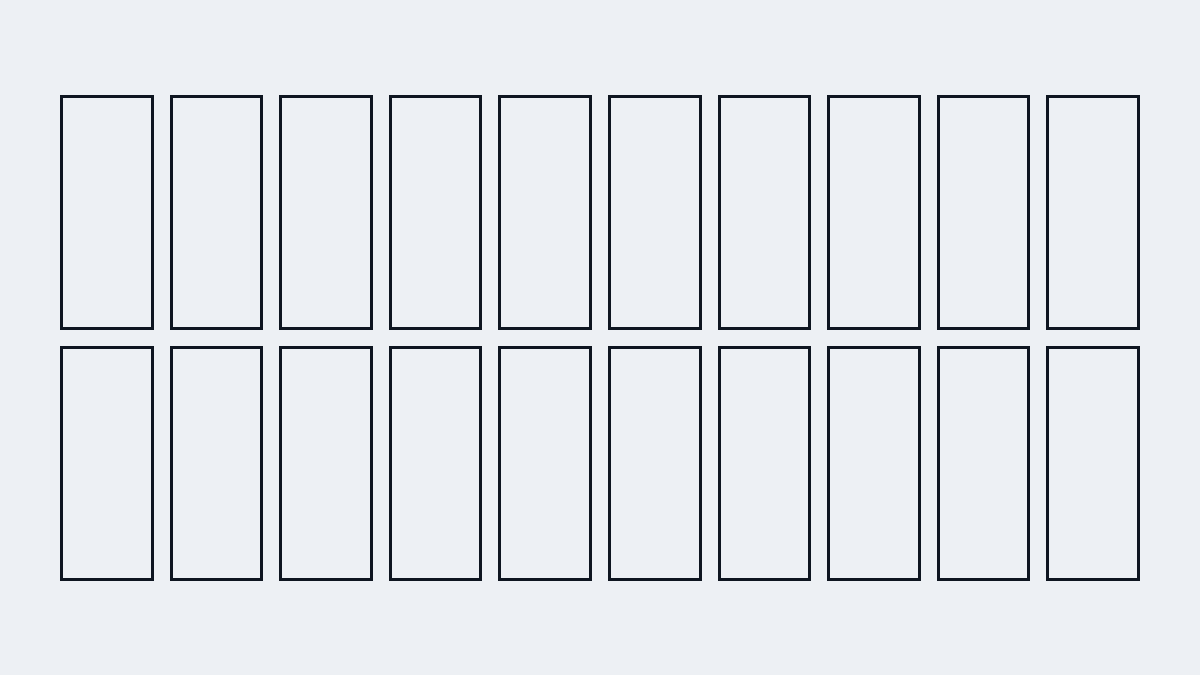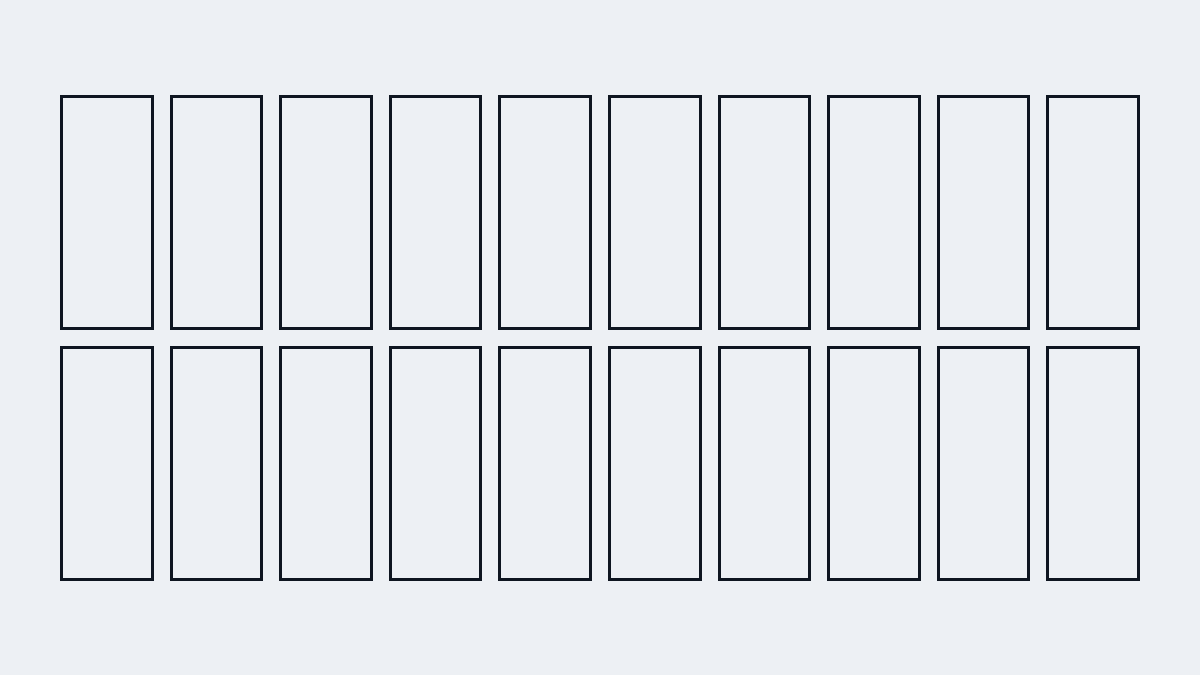
Before that field existed, the honest answer to "which path is producing our output" was a shrug and a reference to the documentation — which said the opposite of the truth.
After the primary path was fixed, the same query is how I know it is actually being used. Every
artifact generated in the last two days records google-stitch, and I did not have to trust that;
I counted.
The honest limitation: the field says which code path ran. It does not say whether that path produced
a good result. A fallback that is being used appropriately and one that is being used because the
primary silently broke look identical in the census — both are just procedural. The census tells
you the proportion changed; it cannot tell you why, and the why is where the defect lives.
What I have not done
The boundary of this article: my measured fallback is an image generation pipeline, not on-device model inference.
The structure is the same — a primary path that may be unavailable, a degraded path that produces acceptable output, and the question of which actually ran. The 303-of-304 measurement is real and it is from that pipeline.
What I have not done is run this against a device fleet. Things I would expect to be harder there and
cannot speak to from experience: capability detection that is honest about thermal availability
rather than just hardware presence, a model that is available at launch and evicted later, and the
fact that a census across real devices needs telemetry rather than a grep over local files — which
reintroduces every question about what you are allowed to collect.
Treat the three-part rule as tested on a pipeline and the device-fleet specifics as reasoning.
The fallback I would not write
One shape I have come to think is a mistake: the fallback that silently produces less of the same thing — truncated output, fewer results, a shorter summary.
It is attractive because it needs no second implementation. It is bad because it is indistinguishable from a correct result for a smaller input, so neither the user nor the census can tell the difference.
A degraded path should be different in kind, not smaller in degree. Different enough that a field can name it, a reader could notice it, and a count means something. If your fallback is "the same thing but less", you have not built a fallback — you have built a quality regression with no name.
What this generalizes to
When you write a second path for the case where the first cannot run, give it three things: a check that decides before the attempt rather than catching a failure, an output good enough to ship on its own merits, and a field on every artifact recording which path produced it.
Then run the count. Not once at design time — periodically, as a number. The failure is never a fallback firing; it is a fallback firing for everything, in a system whose documentation still describes it as the exception.
One post a week, no digest
New writing when it lands. No roundups, no course pitch, no "10 tips".