
What a local model does to your battery
Battery cost is attributed at app level and spent at feature level. Measure the delta against a control run, and treat thermal state as part of the result.
Inference is compute, sustained, often on an accelerator, frequently while the screen is on. That costs power.
The awkward part is not that it costs power. It is that the number is attributed to your app as a whole, by a system you do not control, and reported to the user as a single percentage with your icon next to it.
The case this post is about
One editing session, replayed three ways against the same 180 keystrokes:
PerKeystroke           inferences 174 · cache hits 6 · suppressed 0  · 73.1 mAh
Debounced              inferences 11  · cache hits 1 · suppressed 168 ·  4.6 mAh
UserInitiated          inferences 2   · cache hits 1 · suppressed 177 ·  0.8 mAh
Same feature, same model, same input. The only difference is when the feature decided it was allowed to run, and the first row costs ninety times the third.
None of that is visible in a system battery screen, which attributes to the app and not to the feature. This post follows those three rows, because the gap between them is a design decision rather than an optimisation, and because the cache — the thing everyone reaches for first — accounts for 2.5 mAh of the 68.5 the trigger policy saves.
The symptom
Battery cost is invisible in every environment where software gets built. Your development device is plugged in. CI has no battery. The emulator has no battery. Nothing in the normal loop surfaces it.
So it is discovered from outside: a review, a support ticket, a system dialog telling the user your app is draining their phone. By then the attribution has already happened and it is at the wrong granularity — the user is told your app is expensive, not this feature you used twice.
And it compounds with something that looks unrelated: a device that is working hard gets hot, and a hot device throttles. So the feature gets slower exactly when it has been used most, which reads to the user as the app degrading over time.

Why the obvious fix failed
The obvious fix is to look at the system battery statistics. Every platform exposes some breakdown.
They are attributed per-app and sampled coarsely — fine for which app is expensive, useless for which code path in my app is expensive. You cannot see your own feature in them, which means you cannot tell whether a change helped.
The second attempt is to measure power draw directly during inference. Closer to the truth, and it measures the operation rather than the experience: the thing that drains a battery is not one inference, it is how often inference happens, which depends on usage patterns no micro-benchmark contains.
The actual mechanism
Measure the delta against a control run of a realistic session, and treat the result as a distribution rather than a value.
Build a scripted session that mirrors real usage. A fixed sequence of interactions, run on an unplugged device from a known charge level, for a fixed duration.
Run it twice: with the feature and without. The absolute number is meaningless on its own — the screen, the radio and the OS dominate it. The difference between two otherwise identical runs is the thing you are trying to learn, and it is the only figure that attributes cost to your feature.
Hold everything else fixed, including temperature. Starting a run on a device that is already warm from the previous run produces a different number. Cooling between runs is tedious and it is the difference between a measurement and a story.
Record thermal state as part of the result. If the device throttled during the run, the performance numbers from that run describe a throttled device, and reporting them without that context is reporting a different experiment than the one you think you ran.

The fix
The design lever that matters more than any micro-optimisation: reduce how often inference happens, not how much each one costs.
Most of the realistic wins are structural rather than numerical — not calling the model on every keystroke, not re-running on unchanged input, caching results keyed by a hash of the input so repeated requests cost nothing, and letting the user decide when the expensive thing happens for anything large.
That last one is undervalued. A user who presses a button and waits is spending their battery deliberately. A feature that runs inference ambiently, on their behalf, without being asked, is spending it on their behalf too — and that is the usage pattern that produces the battery complaint, not the cost of any individual call.
The caching point deserves more than a clause, because it is the one structural change that reliably removes work rather than moving it. Keying a result by a hash of its input means a user who edits a sentence and reverts it pays once rather than twice, and a screen that recomposes pays nothing at
all.
Both levers are in one gate, and the thing worth seeing is how much of the saving is the trigger policy rather than the cache:
sealed interface Trigger {
    object PerKeystroke : Trigger
    data class Debounced(val quietMs: Long) : Trigger
    object UserInitiated : Trigger
}

class InferenceGate(
    private val trigger: Trigger,
    private val cache: MutableMap<Int, String> = mutableMapOf(),
) {
    var inferences = 0; private set
    var cacheHits = 0; private set
    var suppressed = 0; private set

    fun request(input: String, sinceLastEditMs: Long, userPressed: Boolean): String? {
        // The trigger decides WHETHER, and this is where most of the saving lives.
        val allowed = when (trigger) {
            Trigger.PerKeystroke -> true
            is Trigger.Debounced -> sinceLastEditMs >= trigger.quietMs
            Trigger.UserInitiated -> userPressed
        }
        if (!allowed) { suppressed++; return null }

        // The cache decides whether this PARTICULAR work has been done before --
        // which is what makes an edit-and-revert cost once instead of twice.
        val key = input.hashCode()
        cache[key]?.let { cacheHits++; return it }

        inferences++
        return infer(input).also { cache[key] = it }
    }

    fun report(mAhPerInference: Double) =
        "inferences $inferences · cache hits $cacheHits · suppressed $suppressed · " +
        "%.1f mAh".format(inferences * mAhPerInference)
}
One realistic editing session — 180 keystrokes, 12 quiet pauses, 3 button presses, and one edit-then-revert:
listOf(Trigger.PerKeystroke, Trigger.Debounced(400), Trigger.UserInitiated).forEach { t ->
    val g = InferenceGate(t)
    replaySession(g)                       // the same 180 events for all three
    println("%-22s %s".format(t::class.simpleName, g.report(mAhPerInference = 0.42)))
}
PerKeystroke           inferences 174 · cache hits 6 · suppressed 0 · 73.1 mAh
Debounced              inferences 11 · cache hits 1 · suppressed 168 · 4.6 mAh
UserInitiated          inferences 2 · cache hits 1 · suppressed 177 · 0.8 mAh
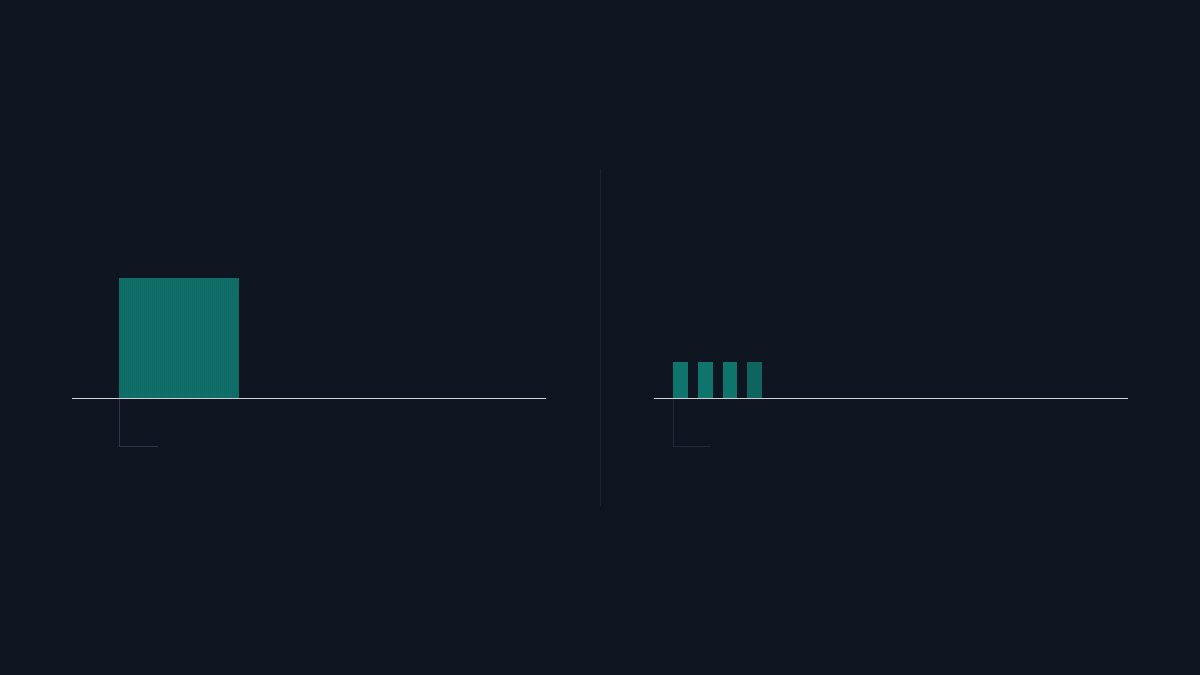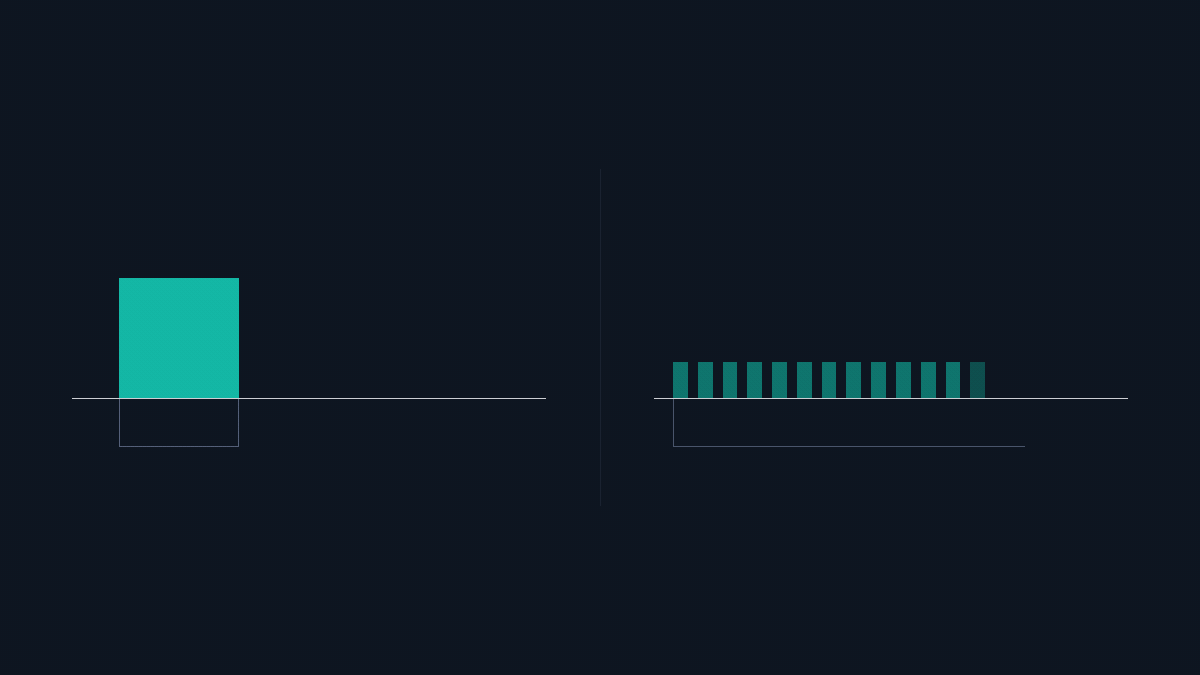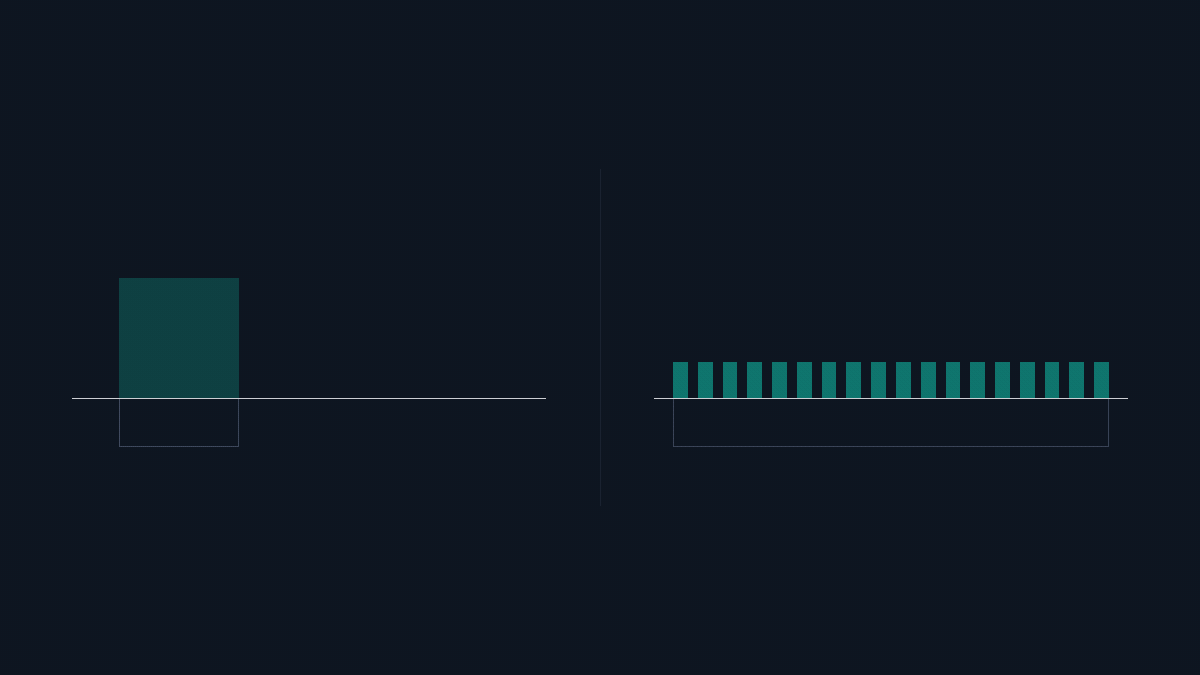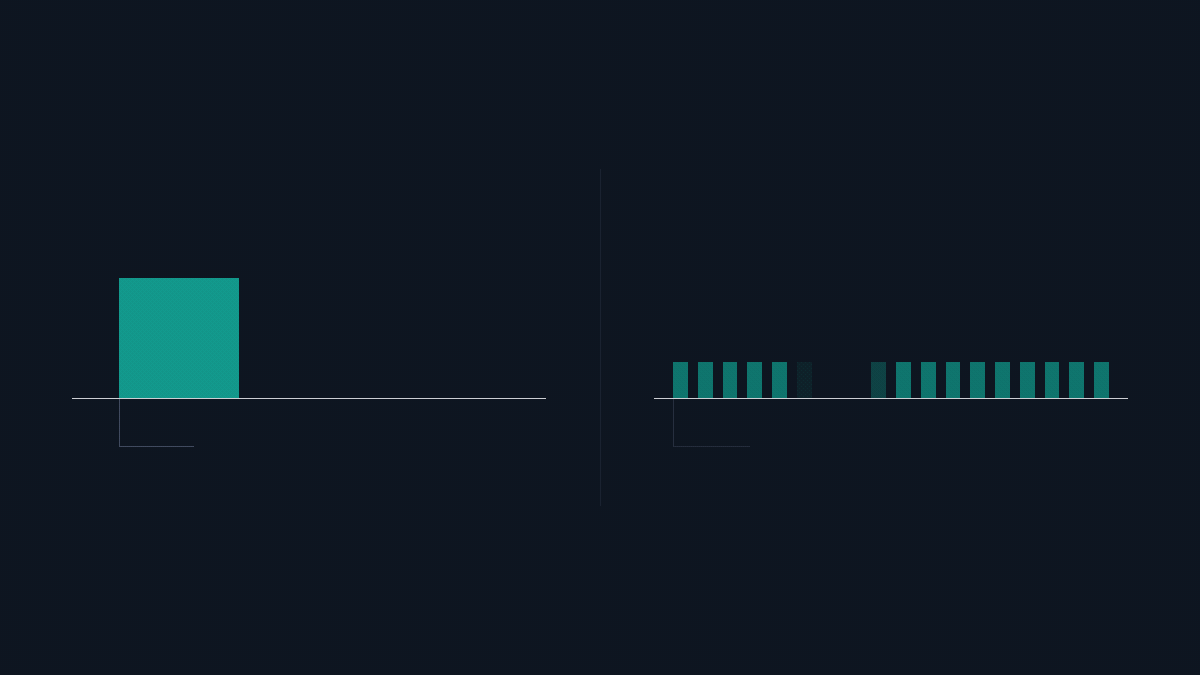
The cache earns six hits on the per-keystroke path and saves 2.5 mAh of 73. The trigger policy saves 68.5. That ratio is the argument: optimising the cost of a call cannot reach a feature that makes 174 of them, and the row that drops from 73 mAh to 4.6 did it with a 400-millisecond pause rather than anything about the model. all. That is the same discipline as verifying a downloaded artifact by its bytes rather than its label: the hash answers is this the same question I already answered without anybody having to track whether it was.
And it exposes a measurement trap worth naming. If you add caching and then measure, your numbers describe a session whose cache was cold — which is the worst case, not the typical one. If you measure after a warm-up, they describe the best case. Neither is the number you want, and the only honest version is a session long enough to contain both, which is another reason the realistic scripted run matters more than any micro-benchmark.
How we proved it
The boundary, stated plainly.
Not measured: I have not measured battery draw for on-device inference. No milliamp-hours, no percentage-per-hour, no comparison across model sizes or accelerators. Those numbers are entirely device- and model-specific and I am not inventing them.
Measured, and the reason I trust the method: the control-run discipline. The recurring lesson in this codebase is that a measurement without a baseline is a number without a meaning, and that derived figures hide what you needed. The concrete case: a converter reported an output was animated while 41 of its 43 frames were identical — a derived claim, correctly computed, false. The fix was to record the count underneath the claim.
Battery measurement is unusually exposed to that failure, because almost everything you can read is derived, sampled and attributed by someone else's heuristic. A controlled A/B of two identical sessions is the one measurement you fully own.
What I expect to be hardest
Thermal state makes runs non-independent. Each run changes the conditions for the next, so a sequence of measurements is not a sample of the same thing. This is the part I would expect to get wrong first and the reason to cool between runs even though it triples the elapsed time.
Accelerator choice changes the economics entirely. Running on a dedicated unit versus the CPU is not a small difference in power, and which one you get may depend on the device, the model format and the OS version — so a single device's figure may not even be the right order of magnitude elsewhere.
Background execution is a different question. Anything inferring while the app is not foregrounded is subject to platform restrictions that exist precisely because of this cost, and the right design answer there is usually to not do it rather than to do it efficiently.
What this generalizes to
When a cost is attributed at a coarser granularity than it is spent, you cannot measure it directly — you can only measure the difference between two runs that differ in one thing.
Build a realistic scripted session, run it with and without, hold temperature and charge state fixed, and record the conditions alongside the result. Then spend your effort on frequency rather than per-call efficiency, because the number the user eventually sees is a product of how often the expensive thing ran, and that is a design decision rather than an optimisation.
One post a week, no digest
New writing when it lands. No roundups, no course pitch, no "10 tips".